Tencent Hy and Inferact Collaborate to Serve Hy4 in Production and Bring Hy4 Preview to vLLM
Announcement
November 2026
All Posts
Announcement
November 2026
Inferact Now Serves More Than 7 Trillion Tokens a Day
Announcement
November 2026
Moonshot AI and Inferact Partner to Advance Kimi Production Serving with vLLM—from energy to intelligence
Announcement
October 2026
MiniMax and Inferact Partner to Accelerate Open Intelligence with Everyone
Engineering
October 2026
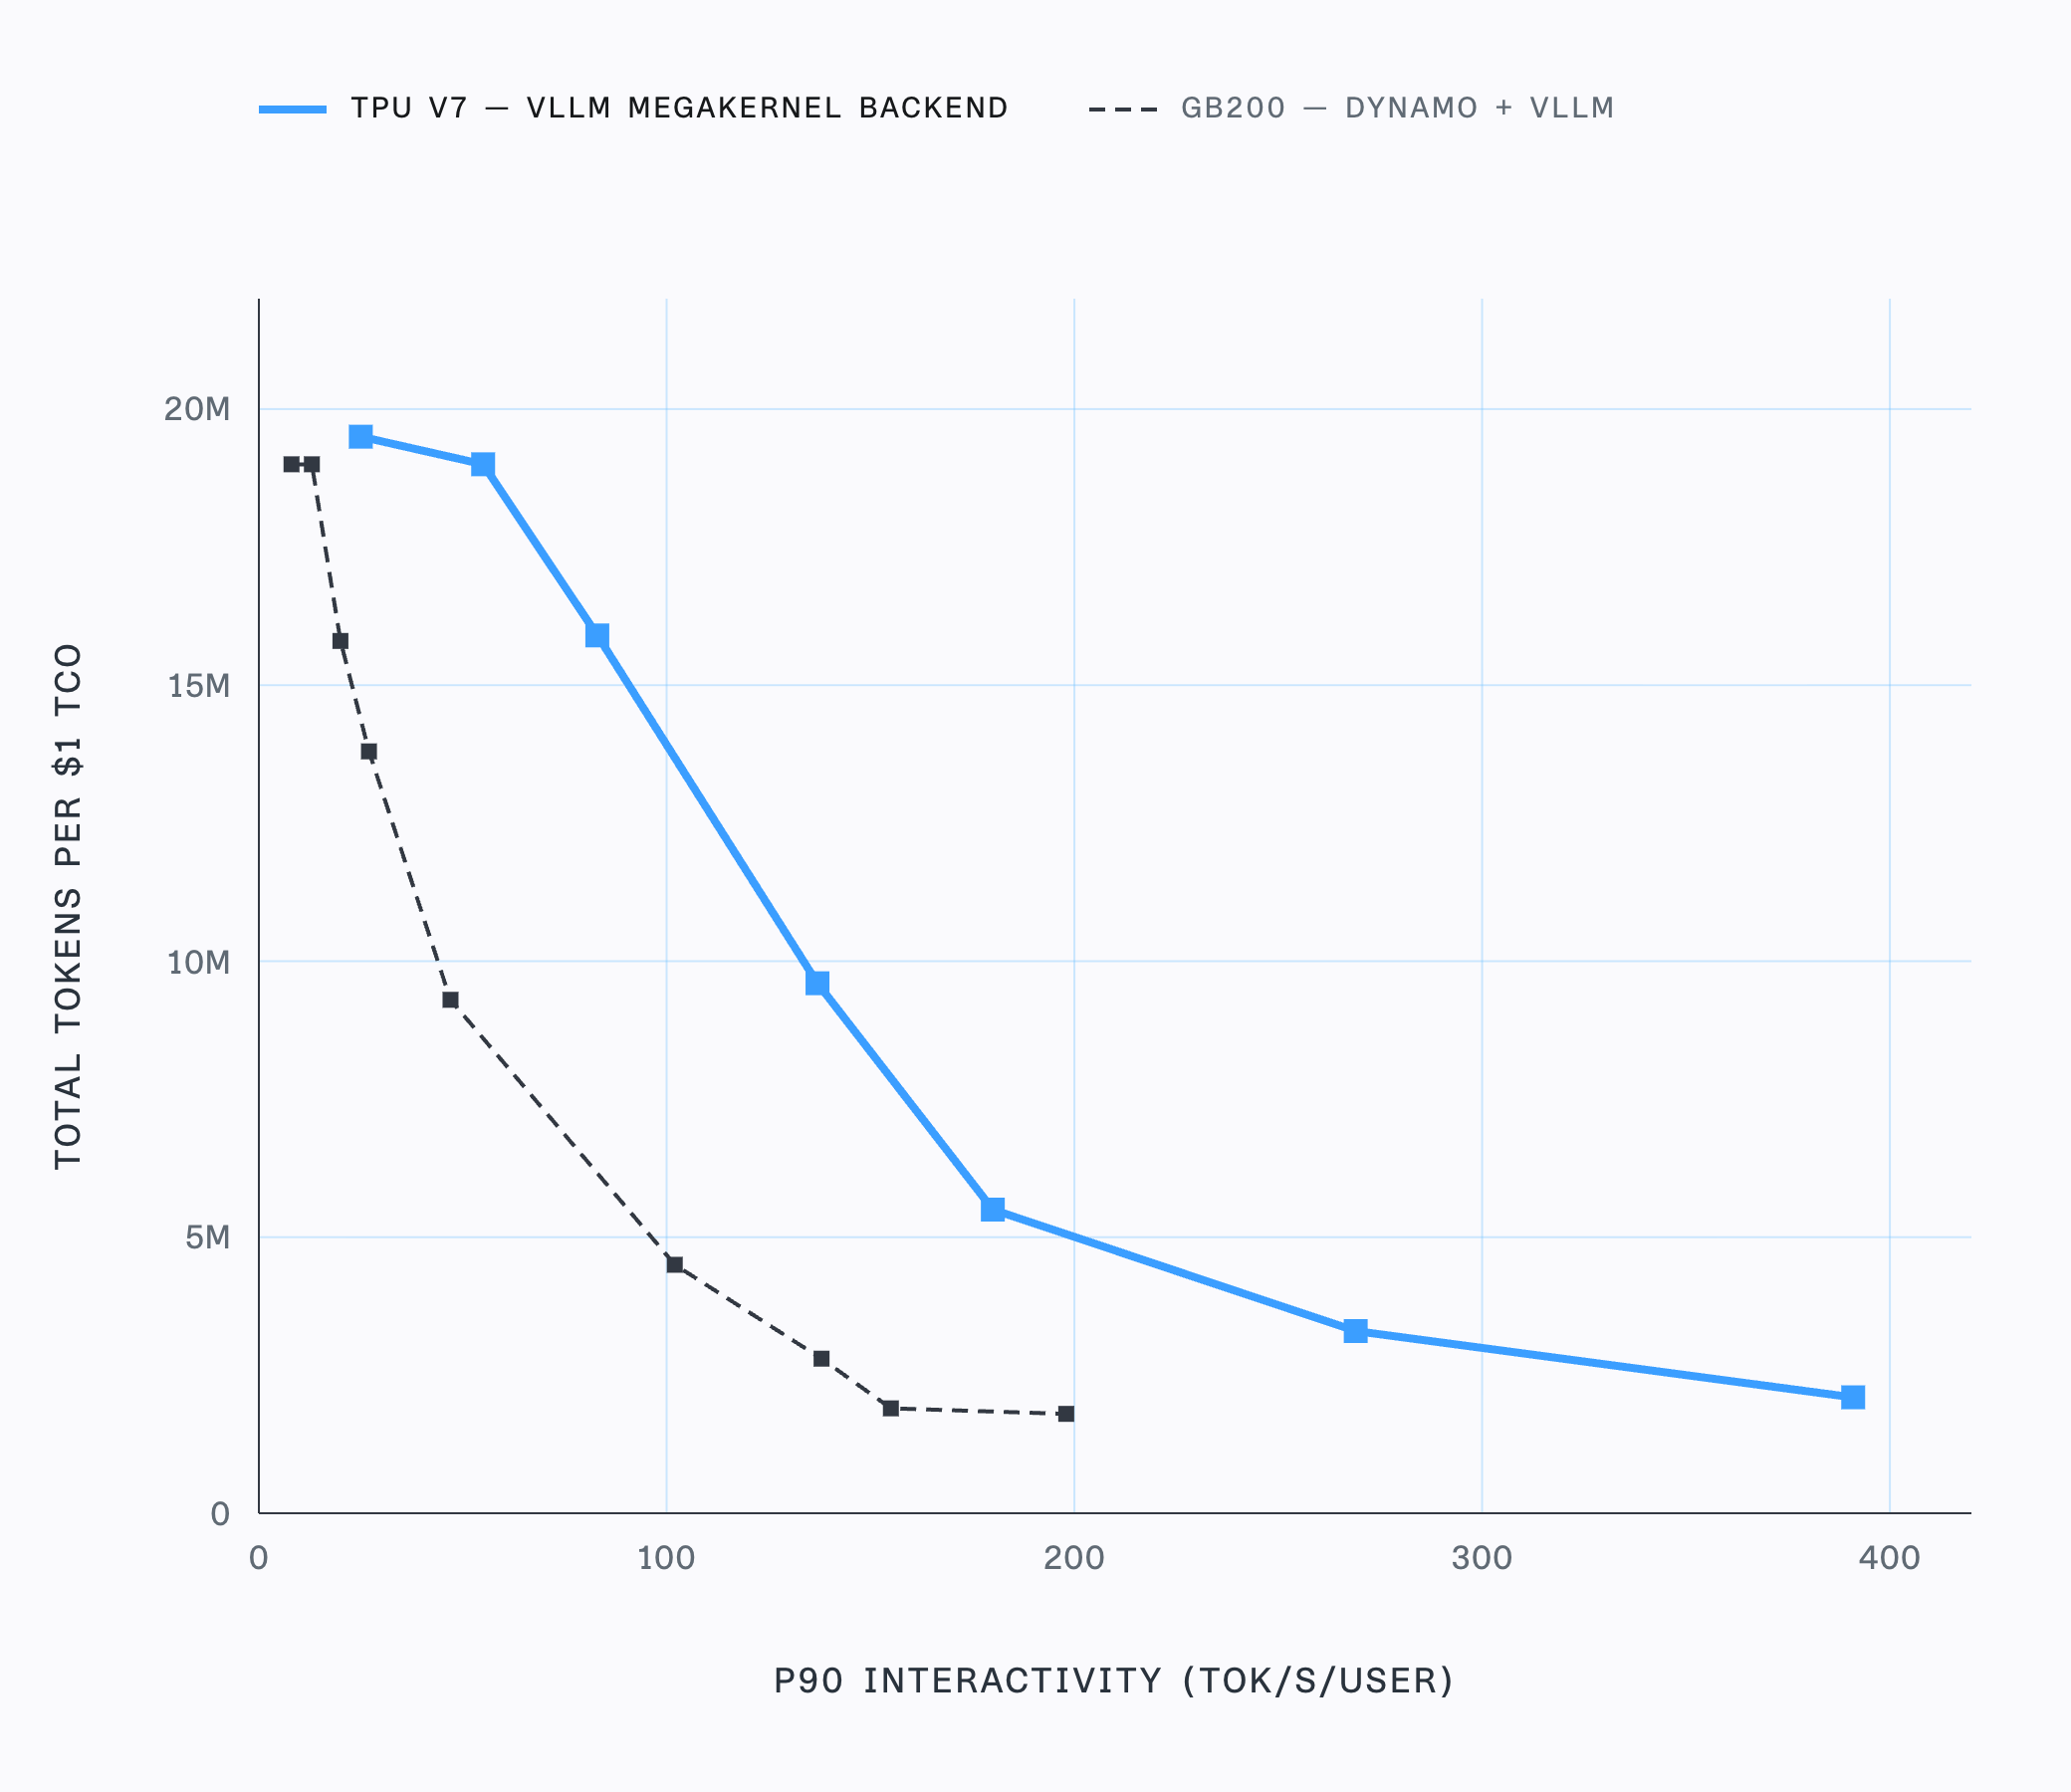
Serving agentic workloads with TPU megakernels in vLLM
Announcement
October 2026
Inferact Collaborates with AMD to Expand Agentic Inference to vLLM on AMD Instinct™ GPUs
Inferact and AMD are collaborating to optimize vLLM for production and agentic inference on AMD Instinct GPUs, with all work landing in open source.
Engineering
September 2026
700 TPS on Kimi K3: A Case for TPU Megakernels
How whole-model visibility, explicit VMEM staging and cross-layer prefetching push TPU v7 decode throughput past the GB200 baseline.
Announcement
September 2026
Google and Inferact Announce Engineering Partnership to Make TPU a First-Class Target for Open Inference
Google Cloud and Inferact align on one engineering roadmap to bring production-grade vLLM inference to TPU, with all resulting work upstreamed to open source
Announcement
August 2026
Inferact Announces Full Certification of Kimi K3 Vendor Verification, Bringing Production Inference Stack to Everyone
Inferact is happy to announce full certification of the Inferact Platform for Kimi K3 vendor verification (KVV).
Announcement
January 2026
Introducing Inferact: Building the Future of AI Inference
Inferact, founded by vLLM's core maintainers, raises $150M to make AI inference cheaper and faster for everyone.